Go with your own intelligence - local inference in Go using llama.cpp including hardware acceleration
yzma lets you write Go applications that use llama.cpp for local inference.
Your models run in the same process as your program. No model server is necessary. No C compiler is necessary. Use the hardware acceleration that your machine has.
See it run, now
A model in your browser. No install, no signup, and no server.
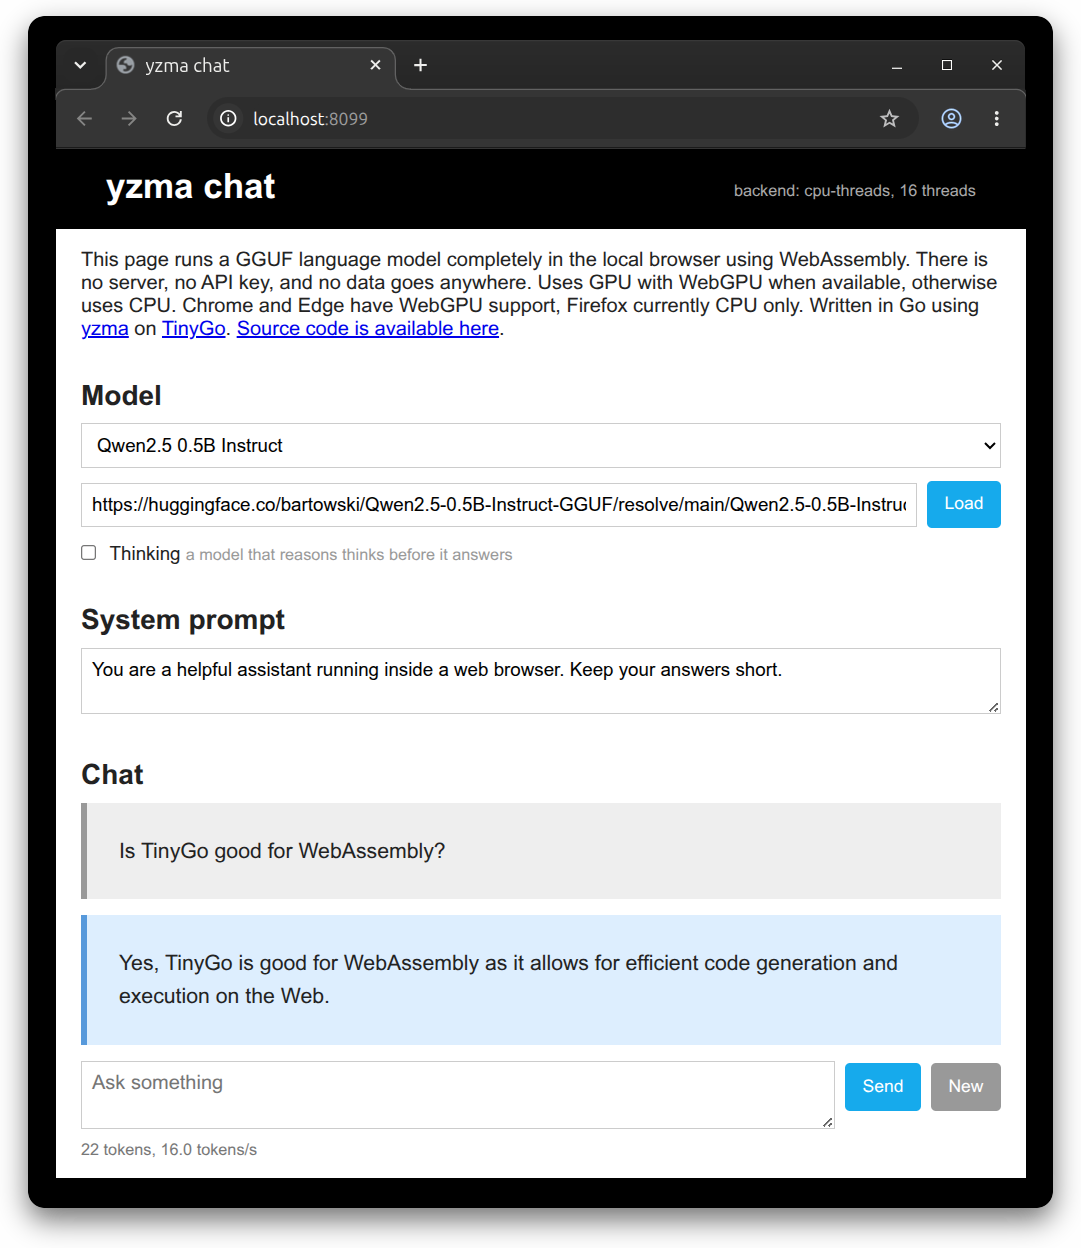
The page downloads the model one time and then runs it on your machine. Chrome and Edge use the GPU with WebGPU.
Powered by yzma
These projects build on yzma.
Talking Heads From The Year 2053
First show whose actors use Physical AI running locally on Arduino UNO Q.
yzma uses the purego and ffi packages, so CGo is not necessary. Build your programs with the normal go build and go run commands.
Ready to get started? Click here.